2025 — 2026
Speech & AI workflow platform
Meeting recording, transcription and AI processing in one system. From conference bots to custom LLM workflows and local inference.
Architect and primary developer of AI subsystems
The challenge
Separate processing modules duplicated code and competed for compute resources. Each new AI feature required its own implementation.
What I built
- Built recording bots for Zoom, Google Meet and Yandex Telemost, with a Docker container for each meeting.
- Unified transcript processing and research jobs in a shared LLM Task engine.
- Developed multi-step workflows, structured responses and long-recording processing.
- Built a local-model gateway, telemetry and management interfaces; integrated transcript chats.
Results
- Three meeting platforms connected to one recording and processing workflow. (3 platforms)
- Different AI tasks run through a shared engine and resource pool.
- Tasks, models and servers can be monitored through management interfaces.
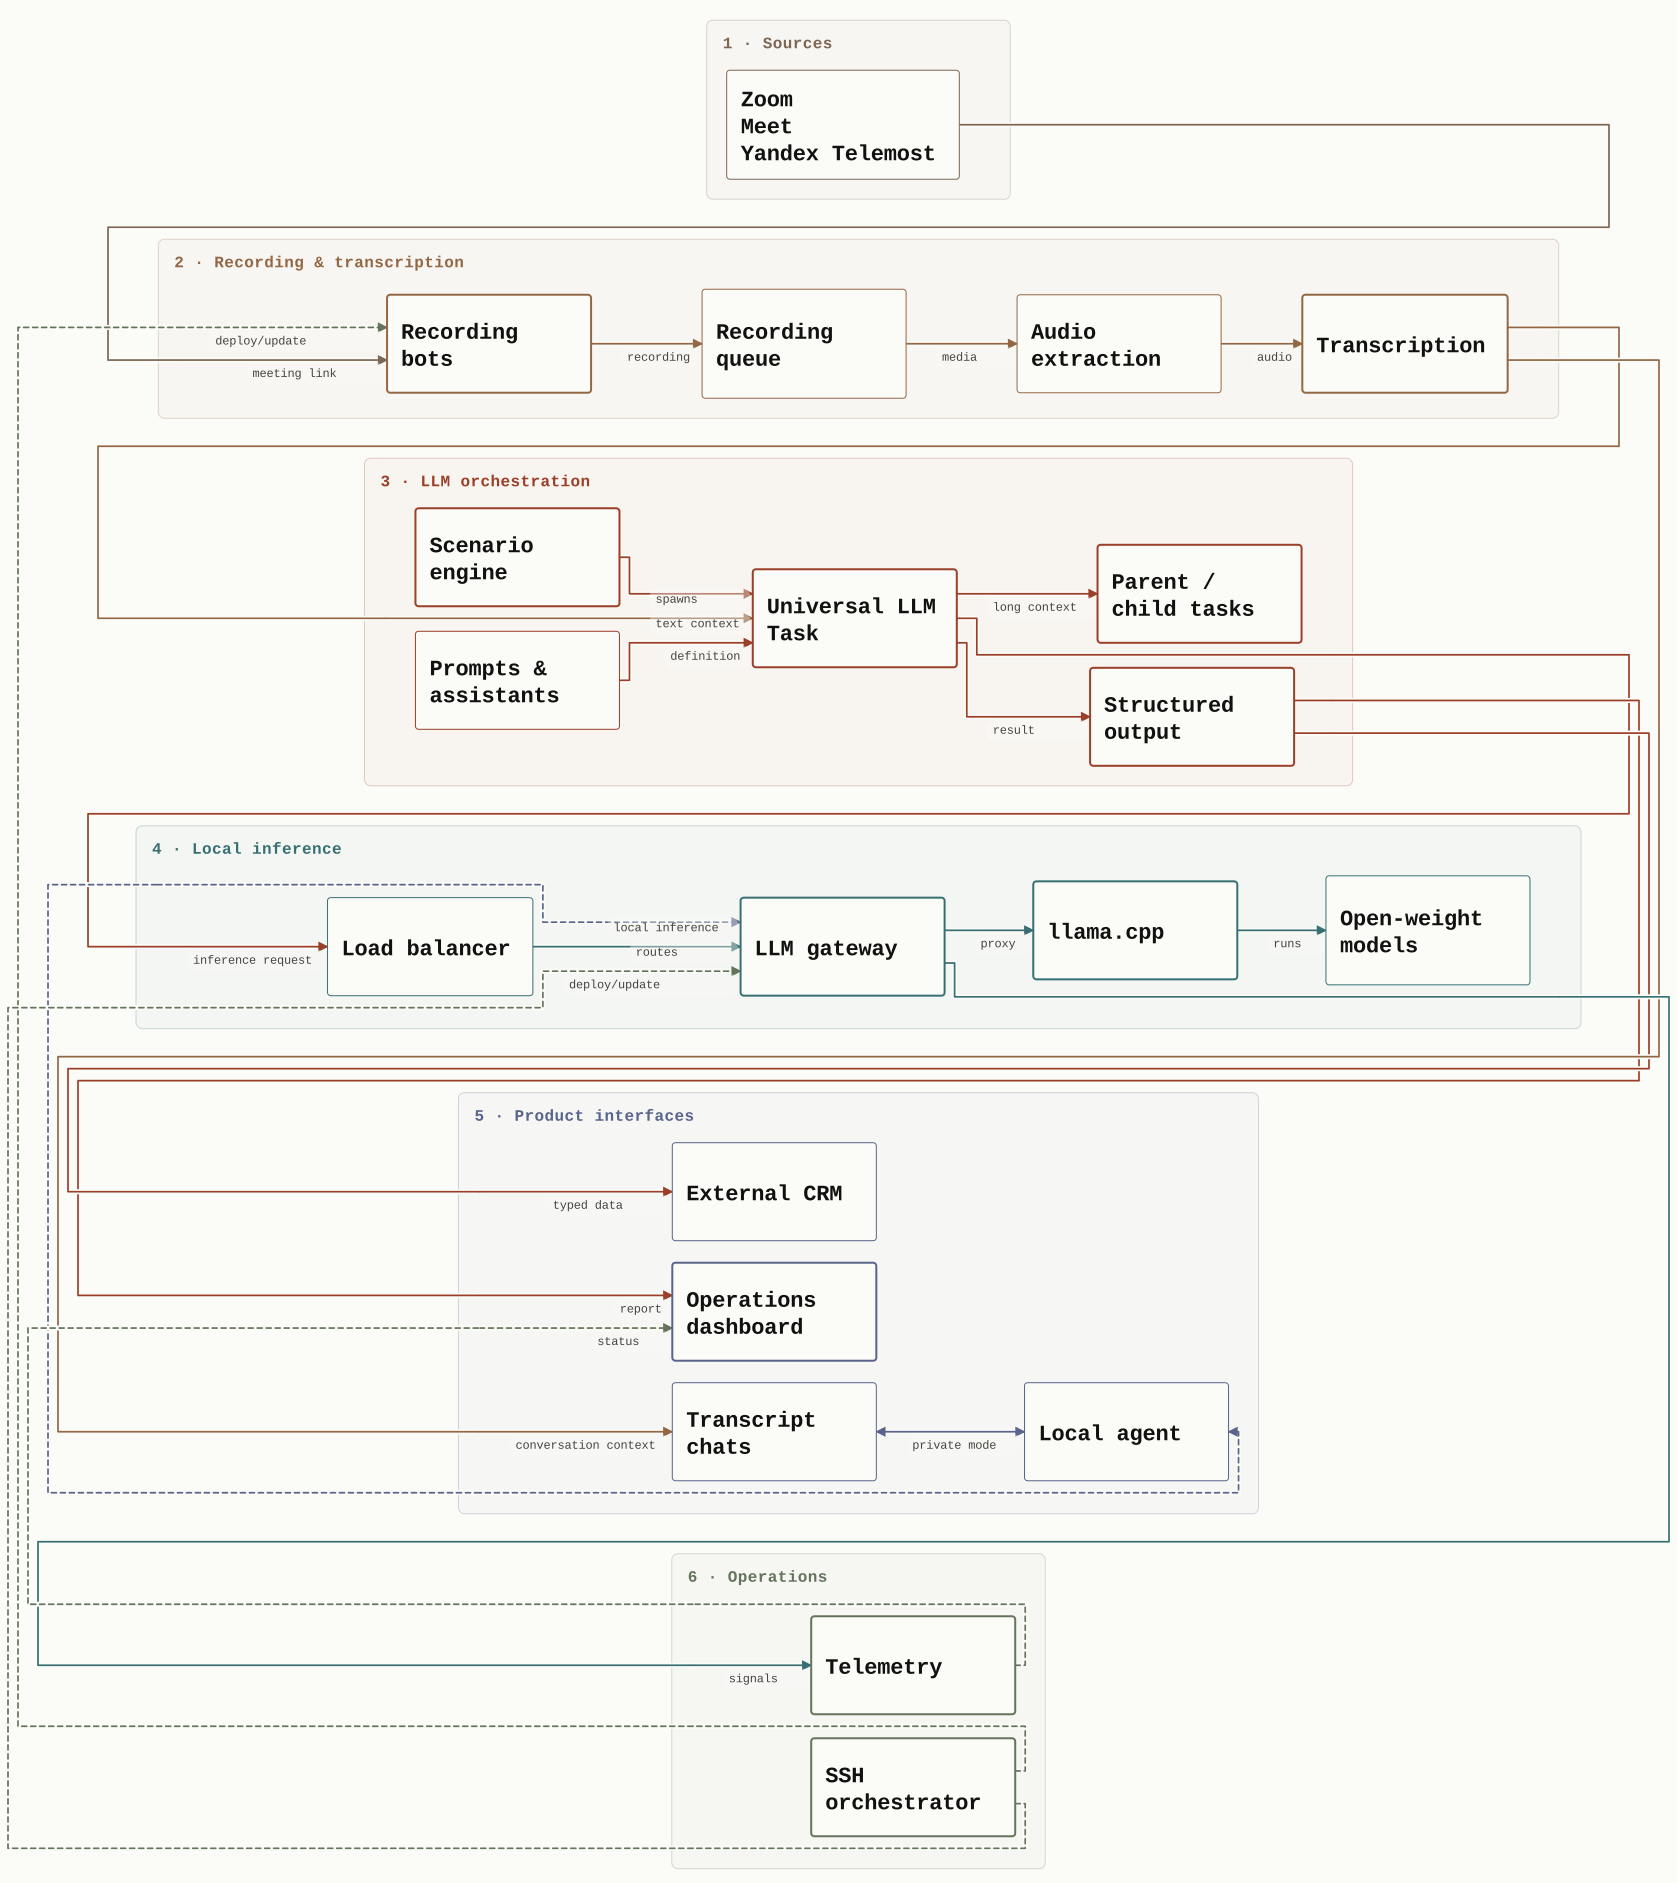
Components & connections
Sources
- Zoom · Meet · Yandex TelemostMeeting sources.
Recording & transcription
- Recording botsOne isolated container per active meeting.
- TranscriptionText and timing from a recording.
- Recording queueAsynchronous media processing.
- Audio extractionPrepare audio for transcription.
LLM orchestration
- Universal LLM TaskShared execution model for AI tasks.
- Parent / child tasksSplit long context and aggregate results.
- Scenario engineSequential and conditional AI workflows.
- Structured outputParse model responses into typed results.
- Prompts & assistantsInstructions and response configurations.
Local inference
- LLM gatewayEntry point for local inference and telemetry.
- llama.cppRuntime for local open-weight models.
- Load balancerRoute requests to available inference endpoints.
- Open-weight modelsLocally hosted language models.
Product interfaces
- Operations dashboardTasks, reports, recordings and infrastructure status.
- Transcript chatsQuestions about individual recordings.
- Local agentContainerized agent using local inference.
- External CRMRecording, transcript and structured report integration.
Operations
- TelemetryInference, task and server status.
- SSH orchestratorInstallation, updates and health workflows.
- Zoom · Meet · Yandex Telemost→Recording botsmeeting link
- Recording bots→Recording queuerecording
- Recording queue→Audio extractionmedia
- Audio extraction→Transcriptionaudio
- Transcription→Universal LLM Tasktext context
- Universal LLM Task→Parent / child taskslong context
- Prompts & assistants→Universal LLM Taskdefinition
- Scenario engine→Universal LLM Taskspawns
- Universal LLM Task→Load balancerinference request
- Load balancer→LLM gatewayroutes
- LLM gateway→llama.cppproxy
- llama.cpp→Open-weight modelsruns
- Universal LLM Task→Structured outputresult
- Structured output→Operations dashboardreport
- Structured output→External CRMtyped data
- Transcription→Transcript chatsconversation context
- Transcript chats↔Local agentprivate mode
- Local agent↔LLM gatewaylocal inference
- LLM gateway→Telemetrysignals
- Telemetry→Operations dashboardstatus
- SSH orchestrator→Recording botsdeploy/update
- SSH orchestrator→LLM gatewaydeploy/update
Engineering takeaway
Context
A platform for meeting recordings and local language models.
- Data processing within a local environment.
- Varying availability of compute nodes.
- Recordings longer than a model’s context window.
Approach
Extracted a shared engine from existing features, then progressively connected recording, processing, workflows and infrastructure.
- One task model and a shared resource pool for different AI features.
- Child tasks and aggregation for long context.
- Separate models for prompts, workflows, execution and reports.
Lessons
- Generalization is justified once duplication has been demonstrated, rather than in advance.
- Structured responses connect model output to application contracts.
- Observability and deployment are part of the product, rather than ancillary work.
Stack
- Docker
- Queues / workers
- llama.cpp
- Open-weight LLM
- Nginx / load balancing
- SSH orchestration
- Vue dashboards
- Structured output
Skills
- AI / LLM systems
- Agent workflows
- Prompt engineering
- Structured output
- Local LLMs
- Full-stack development
- Product architecture
- Domain modeling
- Graph structures
- Orchestration
- Event-driven architecture
- Microservices
- Observability
- Python
- Backend engineering
- Queues & workers
- Vue / Nuxt
- Docker
- Linux / SSH
- CI/CD & Git automation
- Nginx / load balancing